ICKYLIN Intelligent Technology (Nanjing) Co., Ltd.
中文Scan to contactTry IC Agent HubRequest a demo
ICKYLIN 中科麒芯Free trial

FDE: model integration and operations

Model integration, deployment and ongoing operations, supported by GPU and model service monitoring

From deployment to ongoing operations

Three layers connect compute and model services, monitoring and distribution, and AI management and applications. Delivery covers GPU resources, model engineering, operations and engineering workflows through five stages.

Delivery experienceDelivery for 10+ customers, covering private models, application integration and operations.

FDE service architecture03 AI management & applications; Orchestrate engineering flows and manage agent skills; Specs & architecture; RTL design; UVM verification; Synthesis & DFT; Physical design; Sign-off; FlowBuilder; Orchestrate flows, call agents / EDA / scripts, pass artifacts and set human review points; Agent execution loop; Define goal; Break down; Run EDA; Analyze; Adjust & rerun; Human review; Applications; ChipLingo; IC Knowledge Base; IC Agent Hub; 02 Monitoring & distribution; Monitor nodes and manage access credentials; GPU health monitoring; Node monitoring & alerts; API Token management; Issue API keys and manage usage; 01 Compute & model services; Provide compute, deploy models and maintain operations; GPU purchase & rental; Model API services; Model engineering; Model adaptation, deployment & operations; GPU operations; Devices & nodes
03 AI management & applications
Orchestrate engineering flows and manage agent skills
Specs & architecture
RTL design
UVM verification
Synthesis & DFT
Physical design
Sign-off
FlowBuilder
Orchestrate flows, call agents / EDA / scripts, pass artifacts and set human review points
Agent execution loop
Define goal
Break down
Run EDA
Analyze
Adjust & rerun
Human review
Applications
ChipLingo
IC Knowledge Base
IC Agent Hub
02 Monitoring & distribution
Monitor nodes and manage access credentials
GPU health monitoring
Node monitoring & alerts
API Token management
Issue API keys and manage usage
01 Compute & model services
Provide compute, deploy models and maintain operations
GPU purchase & rental
Model API services
Model engineering
Model adaptation, deployment & operations
GPU operations
Devices & nodes

Scroll sideways to view the full diagram

FDE service architecture

Five stages of delivery

Start with requirements and resources, agree the scope, verify the deployment and continue into operations.

  1. Requirements

    Review tasks, materials and confidentiality.

  2. Resource review

    Assess models, memory, concurrency and infrastructure.

  3. Planning

    Agree configuration, integration and scope.

  4. Deployment checks

    Verify models, applications and workloads.

  5. Operations

    Monitor, respond, upgrade and optimize.

GPU & model service monitoring

GPU health monitoring supports FDE delivery by bringing together node, GPU and model service information. Engineers can identify anomalies, review trends and investigate incidents. Monitoring scope is agreed for each deployment.

GPU resources and trends

Collect node status, GPU utilization, memory, temperature and power; monitor offline nodes and threshold breaches, then review trends around incidents.
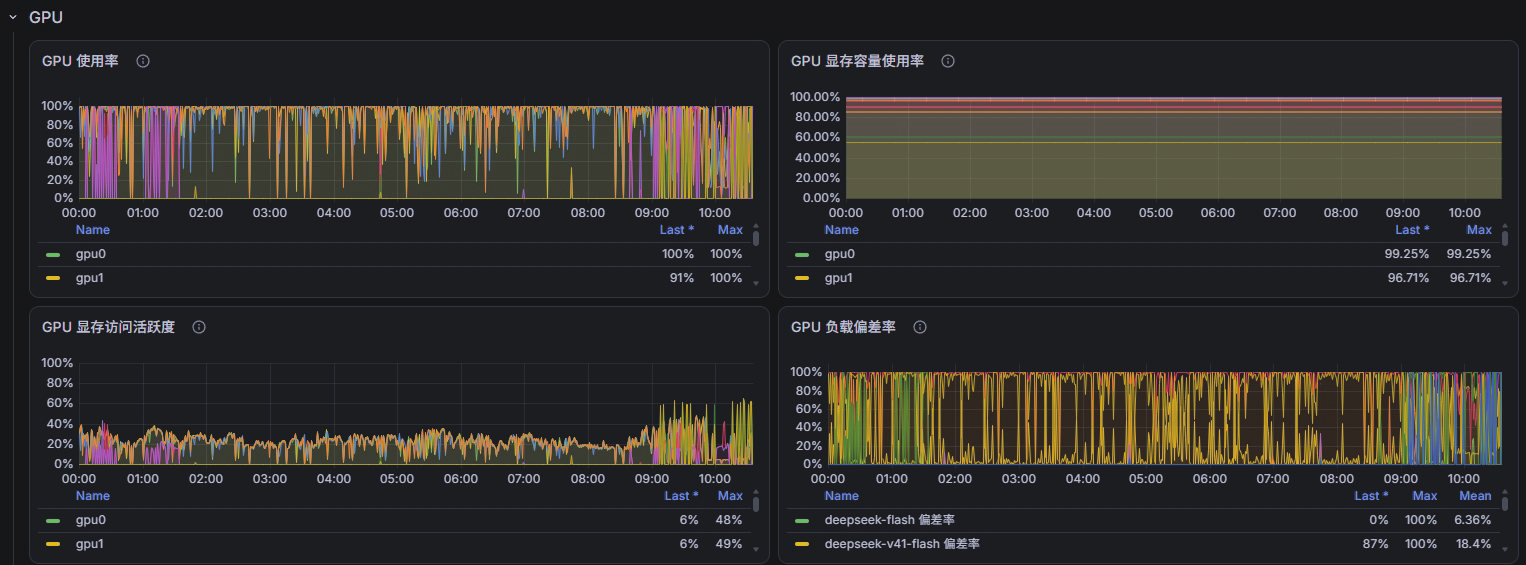
GPU health monitoring interface

Model service status

Use model service probes, HTTP status and concurrent requests to review availability and queuing.
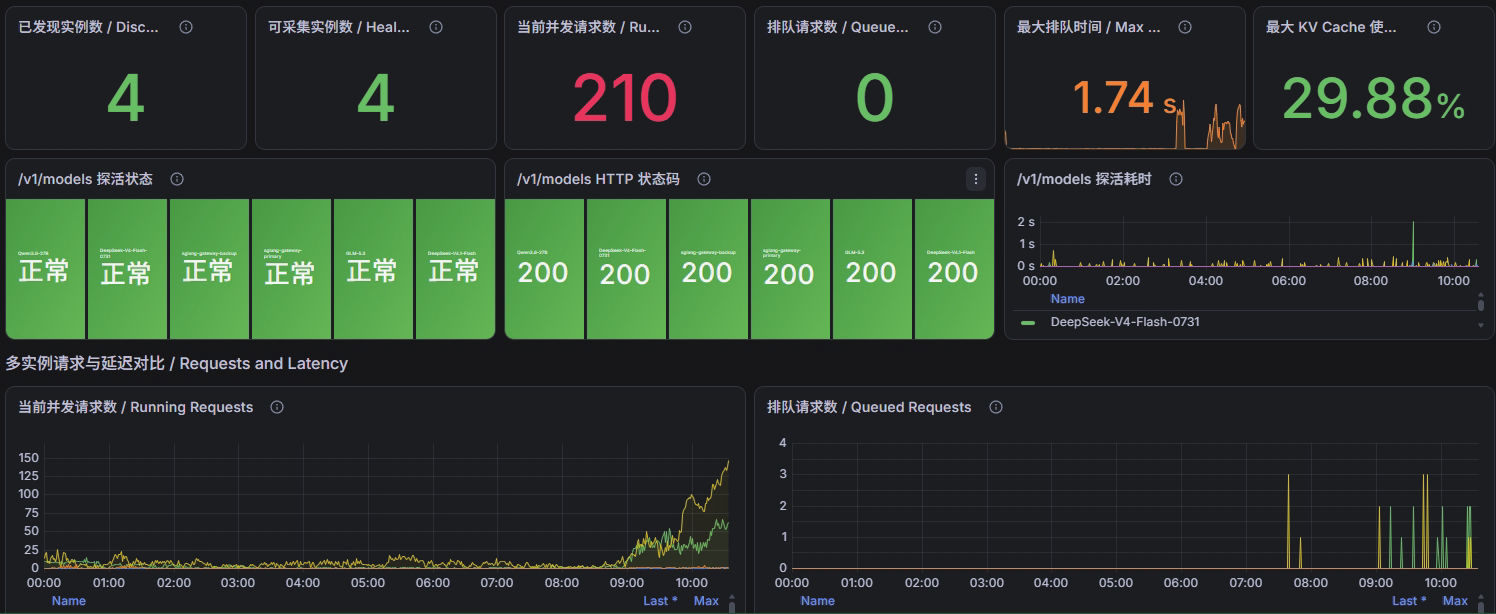
Model service status overview

Request load and response latency

Compare request rate, end-to-end latency, queue time and time to first token as workload changes.
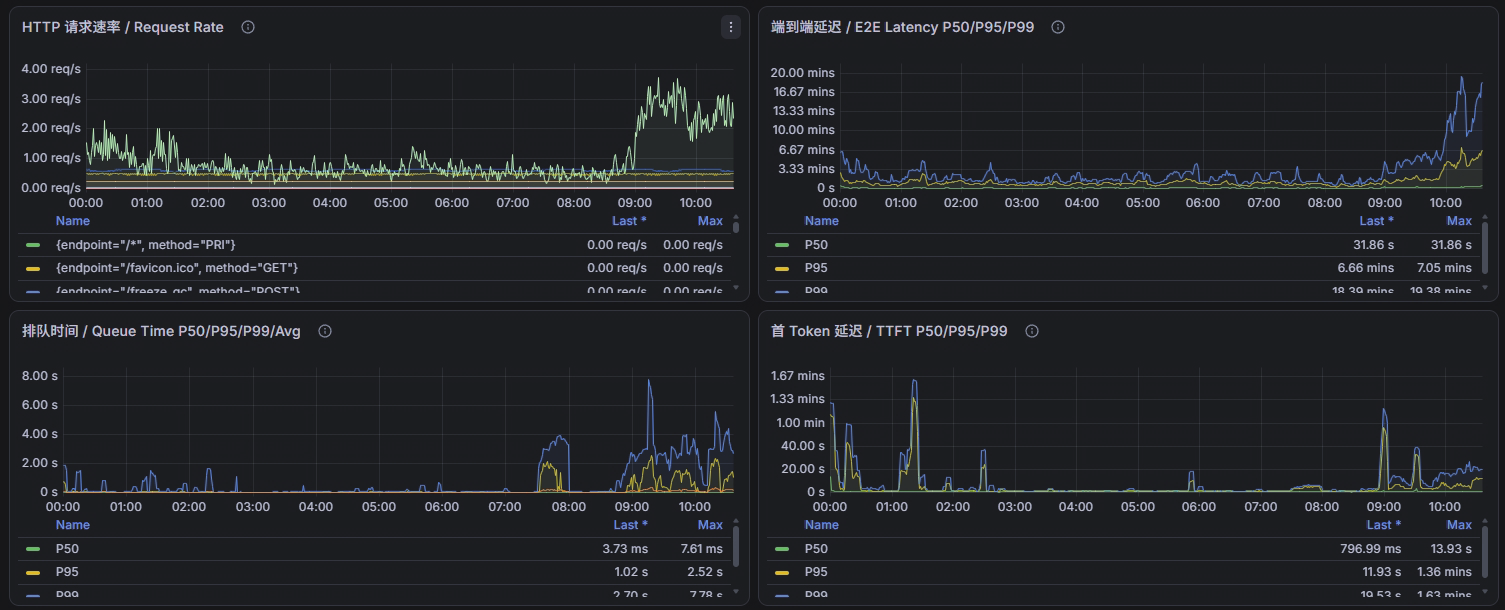
Model service requests and latency

Discuss model deployment and operations

Discuss deployment scope, monitoring and ongoing operations around your compute resources, models and applications.

Contact us